GeomVLA: Unifying Scene, Motion, and Action in 3D
In Conference on Robot Learning, 2026
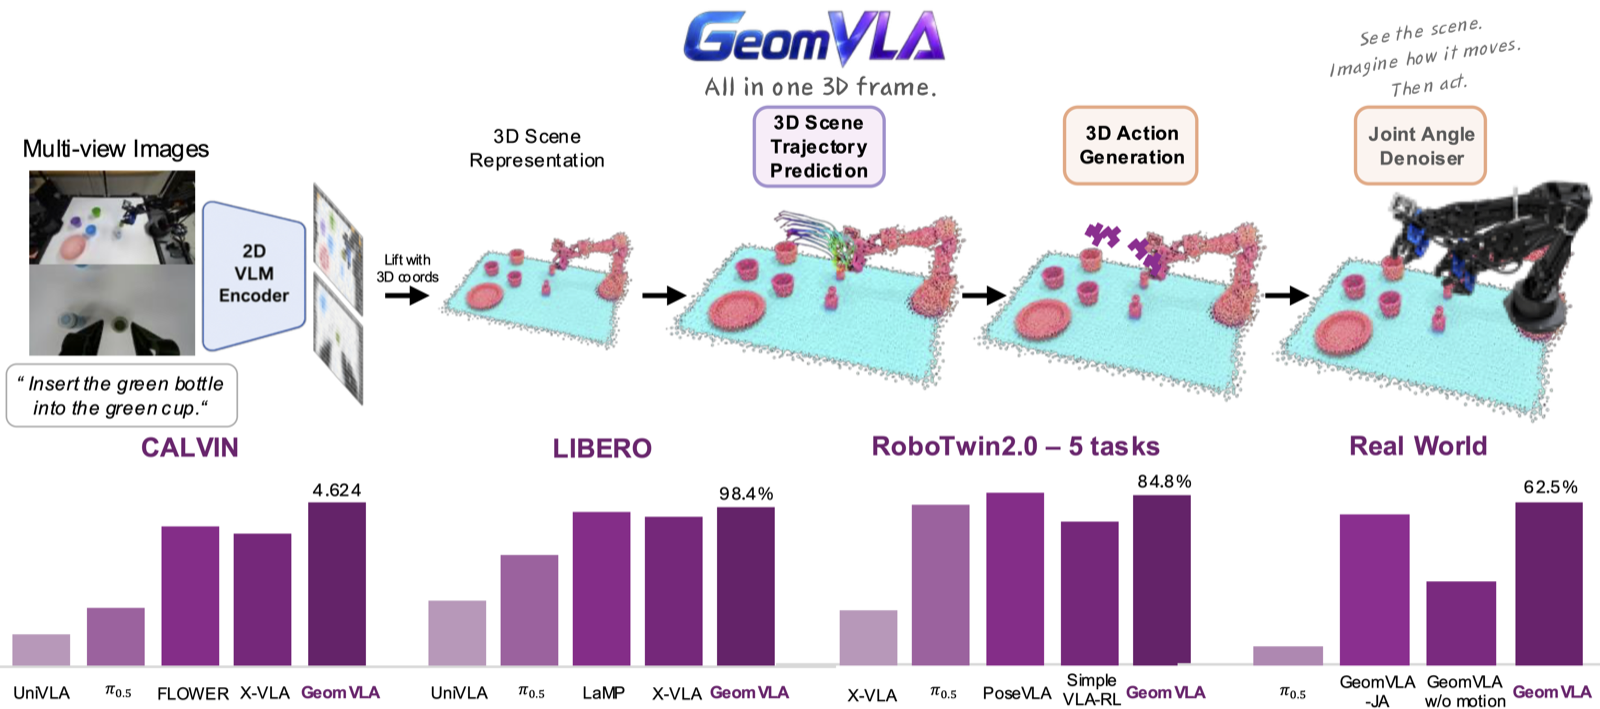
We present GeomVLA, a vision-language-action model that unifies scene perception, latent future scene-motion prediction, and action generation in a shared metric 3D frame. GeomVLA achieves state-of-the-art results on CALVIN and strong performance on LIBERO, RoboTwin2.0, and real-world manipulation without robot-action pretraining.